
AI Research — Field Notes
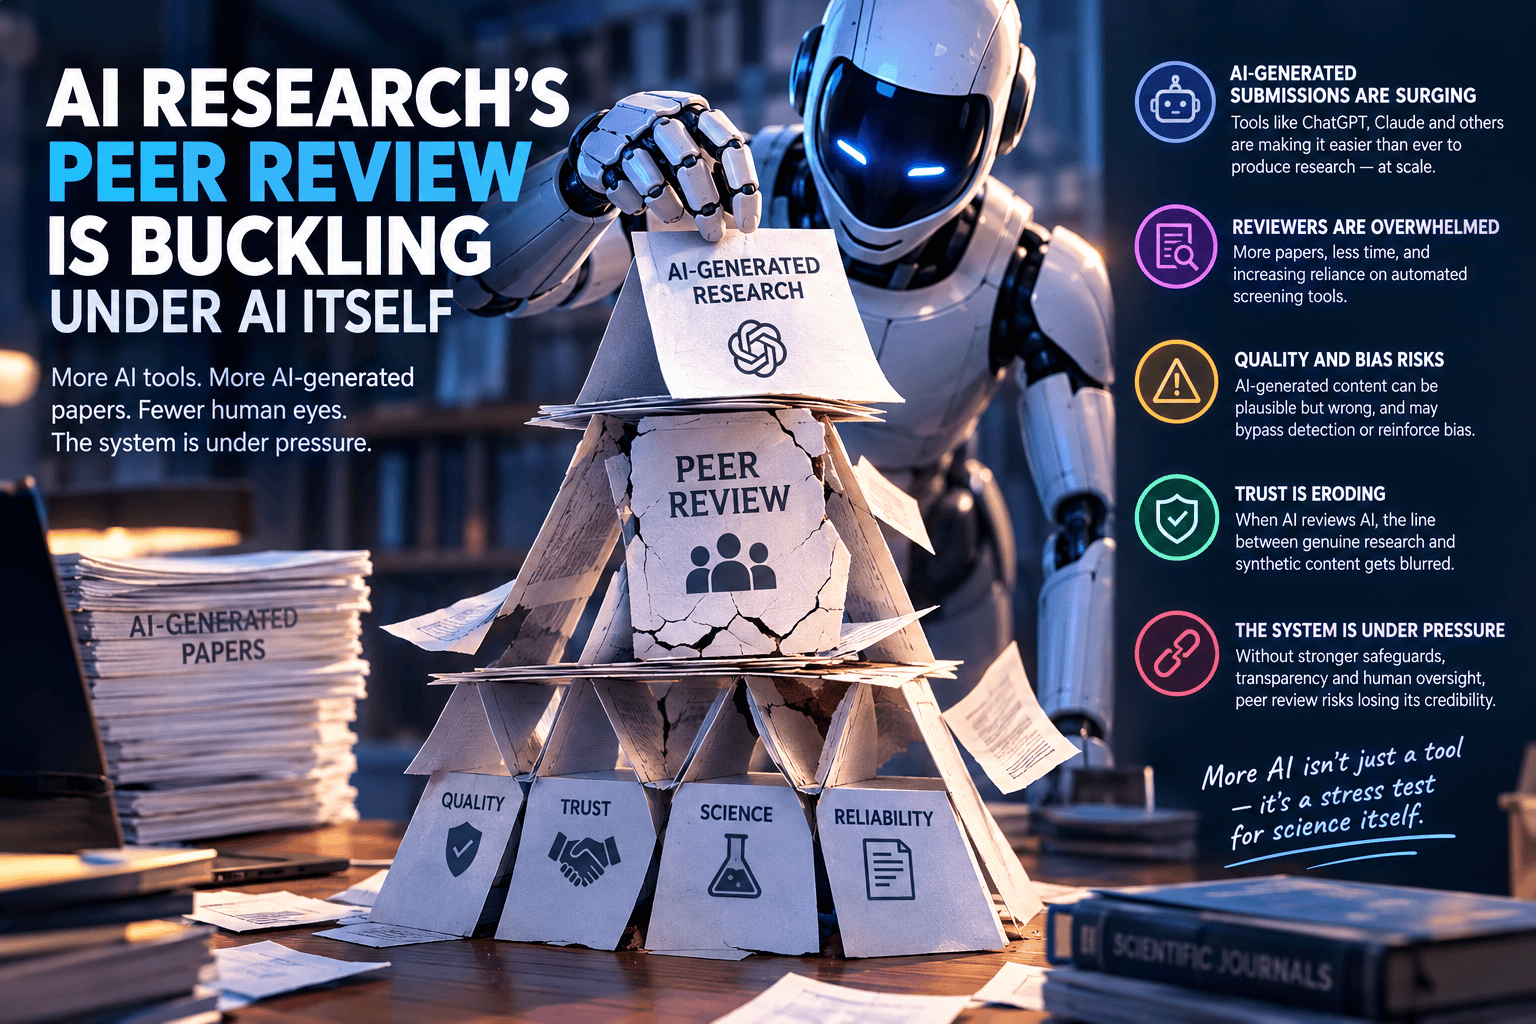
AI conferences are receiving too many submissions for human reviewers to handle, so venues are turning to large language models to draft or supplement reviews — including a conference-wide pilot on nearly 23,000 papers at AAAI-26. Those models agree with each other more than human reviewers do, can be manipulated by hidden instructions planted inside a paper’s PDF, and are being deployed while the field’s underlying reproducibility problem remains unresolved.
AAAI-26, one of AI’s flagship conferences, received more than 30,000 initial submissions — up from roughly 15,000 the year before. NeurIPS and Nature have posted comparable growth. Peer review exists to slow science down long enough to catch its mistakes. It was never built to double in volume every twelve months. So something in the pipeline had to bend, and what bent first was who — or what — does the reviewing.
The reviewer math stopped working first
Training a researcher capable of reviewing a machine-learning paper competently takes years. Submission volume, by contrast, has been compounding. That mismatch is the actual root cause of everything that follows — not a sudden enthusiasm for automation, but a capacity gap that AI happened to be available to fill. Program committees facing tens of thousands of papers and a fixed, slow-growing pool of qualified reviewers reached for the tool that could produce a plausible, detailed review on demand.
ICLR 2026’s official policy permits reviewers to use large language models when writing their reviews. AAAI-26 went further, running what its organizers describe as the first full conference-scale live study of AI-generated reviews on real submissions: every paper that reached full review in the main track — 22,977 of them — received one clearly labeled AI-generated review in addition to human ones, rather than replacing them. A separate detection-vendor analysis from Pangram Labs estimated that around 21% of official ICLR 2026 reviews were entirely AI-generated. That figure is worth treating as directional rather than exact — it comes from an AI-text-detection company, not a peer-reviewed measurement, and detecting AI-generated text is itself an imperfect science.
What an AI reviewer is actually good at, and where it breaks
Researchers who compared human and AI-generated reviews at ICLR 2026 and Nature Communications found that current models can produce fluent, detailed reviews — which explains why exhausted program committees keep reaching for them. But the same comparison surfaced consistent weaknesses: AI reviews skew toward overly positive recommendations, lean on generic criticism that could apply to almost any paper in the field, and sometimes ground their judgments unevenly in the paper’s actual evidence rather than its specific claims.
A more pointed problem shows up in a position paper evaluating automated peer review directly: AI reviewers exhibit what its authors call a hivemind effect — excessive agreement both within a single paper’s review panel and across different papers, which erodes the diversity of judgment that peer review is supposed to provide. Human reviewers disagreeing with each other, for reasons they can each explain, is itself a useful signal about where a paper is weak or ambiguous. An AI reviewer converging on the same verdict as every other AI reviewer removes that signal rather than replacing it with something better.
The same research demonstrated that rewriting a submission with an LLM before resubmitting it can shift an AI reviewer’s score meaningfully — independent of whether the underlying science changed at all. That’s a way to game a score, not a quality improvement, and it works precisely because the reviewer is evaluating prose polish as a proxy for rigor.
A new attack surface: prompts hidden inside the paper
Peer review used to have one attack surface: persuading a human reader. It now has a second one, aimed at the reviewing tool itself. The Japanese newspaper Nikkei identified hidden prompts embedded in at least 17 arXiv preprints — text invisible to a human skimming the PDF but readable by a language model parsing the underlying text layer, instructing it to return only a positive review. Separately, researchers documented submissions in the ICML 2025 review cycle that contained hidden prompts specifically engineered to manipulate LLM reviewers into inflating their scores.
Neither trick would have any effect on a human reviewer reading the rendered page. Both work only because a growing share of the review pipeline is now, at least partially, a language model reading raw text — which means the author of a paper has a direct, previously nonexistent channel to influence the instrument judging their own work.
How venues are actually responding — and it isn’t uniform
There is no field-wide standard yet. Each major venue has picked a different point on the spectrum between “prohibit LLMs entirely” and “give every paper an AI review by default,” and the policies are changing roughly once a year as each new cycle’s organizers reassess.
| Venue | Stance | What it actually permits |
|---|---|---|
| NeurIPS 2025 | Prohibited | LLMs barred from producing the substantive evaluation and decision text of a review |
| FAccT 2025 | Prohibited | Same core-reviewing restriction |
| ICLR 2025 | Optional assist tool | A Review Feedback Agent nudged reviewers on gaps; 27% of reviewers who received its feedback revised their reviews |
| ICLR 2026 | Permitted | Reviewers may use LLMs to help write review text |
| AAAI-26 | Parallel official pilot | Every main-track paper (22,977) received one labeled AI-generated review alongside — not instead of — human review |
| ICML 2026 | Two-policy opt-in | Authors choose, per submission, whether their assigned reviewers may use an LLM to help understand or polish reviews of that specific paper |
The ICML 2026 model is the most granular response so far: it treats the decision as belonging to the author of each paper rather than the venue as a whole, which sidesteps a one-size-fits-all rule but pushes the judgment call — and any downside — onto individual researchers who may not fully understand what they’re opting into.
arXiv’s blunt instrument
Thomas Dietterich, chair of arXiv’s computer science section, announced tightened enforcement against unchecked AI-generated content: authors face a one-year submission ban if a paper shows clear evidence they didn’t verify a language model’s output before submitting it. The evidence threshold is specific — hallucinated references, or literal leftover artifacts like an unedited line reading “Here is a 200-word summary,” are the kind of tells that trigger enforcement.
That followed an earlier move: arXiv began requiring computer-science survey papers to pass peer review before posting, after empirical analysis of over 10,000 arXiv survey submissions found their volume had grown exponentially, with a sharp acceleration once ChatGPT and later Claude, Gemini, and PaLM made it easy to draft long literature reviews quickly.
A ban that triggers on obvious tells punishes carelessness, not AI-assistance itself — a distinction that has split researcher reaction. Some support the crackdown; others have raised concerns about uneven enforcement and about the policy being circumvented through falsely listed co-authors, since the rule attaches to authorship, not to the writing tool used.
The crisis this is layered on top of
Peer review’s job, in theory, is to catch results that won’t hold up before they become citable, fundable, or built upon by someone else’s PhD thesis. That job was already difficult before AI-generated reviews entered the picture, because AI research’s own reproducibility record is uneven. One widely cited estimate — an OECD analysis of AI in science, summarized in an industry report — put the share of irreproducible AI research at around 70%, with problems appearing across image recognition, natural language processing, reinforcement learning, and recommender systems.
A separate, more recent analysis tells a more encouraging but methodologically different story. Researchers who examined 56,800 papers published across five leading AI conferences between 2014 and 2024 found that documentation practices improved sharply over the decade: the share of papers sharing both code and data rose nearly sixfold, from 11% to 64%. Building on that trend, the same researchers estimate — by inference from documentation completeness, not by actually rerunning the experiments — that practical reproducibility rose over the same period from roughly 28% to 64%.
Those two numbers, ~70% irreproducible and ~64% inferred-reproducible by 2024, are not a contradiction so much as a warning about how loosely “reproducibility” gets measured in this field. One figure comes from attempts (or reported attempts) at direct replication; the other is inferred from whether a paper shipped code and data, which is a precondition for reproducibility, not proof of it. A paper can post clean code and still not replicate for reasons that have nothing to do with documentation — different hardware, undisclosed hyperparameter sweeps, or cherry-picked seeds. NeurIPS and JAIR have introduced reproducibility checklists partly for this reason, but a checklist measures whether authors described their method, not whether the method actually works the way they described.
Put the two problems next to each other and they compound rather than cancel out. The mechanism meant to catch shaky, underdocumented, or overstated results — peer review — is the same mechanism now partially delegated to tools that agree with each other by default, can be steered by hidden text, and reward polished prose as a proxy for rigor. A field with a reproducibility gap needs a review process that’s more skeptical, not one running on tools calibrated to sound reasonable about everything.
What to actually do if you’re submitting this cycle
- Assume one of your reviews may be AI-generated at venues that permit it (ICLR 2026, AAAI-26’s parallel track). Write rebuttals that address specific technical claims point by point rather than tone or framing — generic pushback is weak against generic criticism, but a precise correction to a factual misreading is something both a human meta-reviewer and a well-built AI system can weigh.
- Over-document reproducibility artifacts regardless of the venue’s minimum checklist — code, data, exact hyperparameters, seeds, and hardware. It’s the one factor the arXiv documentation study ties to rising reproducibility rates, and it protects you if a reviewer (human or AI) questions whether your result generalizes.
- Check your own PDF’s text layer for stray or invisible text before submitting. Template reuse, drafting-tool leftovers, or copy-paste from another document can leave hidden text that looks identical to a manipulation attempt — exactly the kind of evidence that triggers arXiv’s one-year ban, even when it’s an accident rather than an intent to game a reviewer.
- Read per-submission AI policies literally, not by venue reputation. Under ICML 2026’s opt-in framework, the choice is attached to your specific paper, not a blanket rule — know what you agreed to before you’re in a rebuttal period trying to figure out who reviewed you.
If you’re an early-career or independent researcher without an institutional co-author to satisfy arXiv’s first-time-poster endorsement requirement, arrange that before a deadline crunch, not during one — coordinate with a lab or collaborator willing to endorse, or route through a workshop track with lighter gatekeeping while you build the track record that makes future endorsement unnecessary.
Who this squeezes hardest
The endorsement requirement that keeps first-time arXiv posters from flooding the platform solves one gatekeeping problem by creating another: it’s a structural barrier tied to institutional network, not to the quality of the work, and it falls hardest on researchers outside traditional AI hubs. The hivemind effect in AI-assisted review carries a similar asymmetry — a model calibrated on the existing literature’s center of gravity is, by construction, less equipped to reward work that existing literature actively disagrees about, which is exactly the kind of work peer review is supposed to be able to recognize even when it’s uncomfortable. The capacity that AI-assisted review buys back is real. It’s paid for, at least in its current form, in reduced perspective diversity and in a reviewer that can process volume but can’t independently rerun your experiment on withheld hardware the way an unusually thorough human sometimes will.
None of this makes AI-assisted review a mistake outright — an unreviewed backlog of 30,000-plus submissions arguably fails worse than an imperfect one. What it does mean is that AI research is now running two live experiments on itself at once: whether its own results replicate, and whether the process built to check that can still tell rigorous work from confident-sounding text. Neither question has a settled answer yet, and this cycle’s conferences are the closest thing either question has to a real-time measurement.
Sources
- Fichtl et al., “AI-Assisted Peer Review Across Research Communities,” arXiv:2608.03581 (Aug. 2026) — arxiv.org/abs/2608.03581
- “AI-Assisted Peer Review at Scale: The AAAI-26 AI Review Pilot,” arXiv:2604.13940 — arxiv.org/pdf/2604.13940
- “Stop Automating Peer Review Without Rigorous Evaluation,” arXiv:2605.03202 — arxiv.org/html/2605.03202v1
- Dietterich, arXiv CS-section policy update, reported in TechCrunch, May 2026 — techcrunch.com and The Decoder — the-decoder.com
- Coakley, Snelleman, Hoos & Gundersen, “The Shift Toward Open and Reproducible AI Research,” arXiv:2606.16974 — arxiv.org/abs/2606.16974
- OECD AI-in-science reproducibility estimate, as summarized by AIMultiple — aimultiple.com/reproducible-ai